

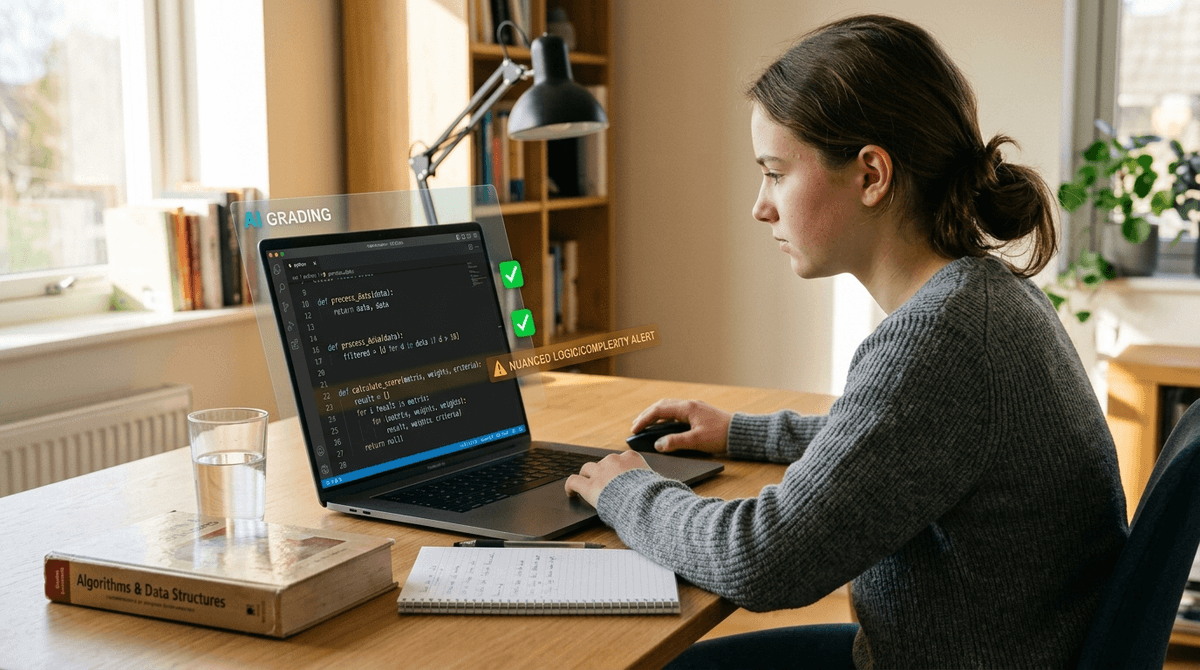
Artificial intelligence can grade introductory coding homework nearly as accurately as university professors—provided it has a strict rubric to follow. When programming problems get complex, however, the machine starts making mistakes that human teachers catch immediately.
Leading AI models agree with human instructors nearly 90% of the time on basic computer programming tasks, but their grading accuracy degrades sharply the moment an assignment demands complex, abstract reasoning.
Schools are increasingly adopting automated feedback tools to speed up homework turnaround, and students are already pasting their code into chatbots to ask "did I do this right?"
If your child uses AI as a late-night tutor or self-grader for computer science, the tool works remarkably well for introductory syntax and basic scripts. But relying on a bot to evaluate complex, multi-step projects gives students a false sense of security—it routinely validates flawed logic once the problem moves beyond routine steps.
Introductory computer science courses are overflowing, and grading hundreds of unique lines of code by hand takes days. Instructors wanted to see if modern large language models could evaluate technical student work reliably without penalizing students who solve problems using clever, alternative commands that were not in the official answer key.
- Rubrics beat raw model power. The clarity of the grading instructions influenced accuracy far more than the specific AI model used. A detailed scoring guide closed the performance gap across different platforms.
- Near-professor agreement on basics. When given precise criteria, top-tier models matched human expert grading on roughly 89% of student responses.
- Smart with alternative methods. The software excelled at spotting "equivalent solutions"—granting full credit when a student arrived at the correct outcome using an unorthodox command sequence.
- Steep drop-off with complexity. While accuracy remained high for routine file-management tasks, it plunged as student tasks advanced toward system administration and multi-layered operations.
A chatbot does not actually execute or run the student's code in a live computer environment; it predicts whether the code looks right based on text patterns.
When an assignment is straightforward, those patterns are rigid and easy to score. The moment your child writes a solution requiring multi-layered architectural logic, the AI begins guessing—and it delivers those guesses with complete confidence.
This study is a preprint from a single university and has not yet undergone formal peer review. The researchers evaluated 1,200 short command-line Linux responses written by college sophomores, meaning these findings cannot guarantee how AI will handle full-length software development, Python apps, or creative web design projects.
- If your child uses a chatbot to check their programming homework...
Have them paste the teacher's exact grading rubric into the prompt, because AI accuracy depends on explicit rules rather than open-ended questions like "how did I do?" - If your student found an unusual coding solution that still works...
Reassure them that automated graders and experienced teachers both recognize valid alternative pathways to the same technical result. - If your child is tackling advanced, multi-step programming assignments...
Instruct them never to rely on an AI's stamp of approval, and instead test their code directly in the terminal or ask a human teacher for feedback.
Let your student use AI to catch simple syntax bugs and sanity-check basic coding drills, but make sure they never outsource final project verification to a chatbot.
Manuel Alonso-Carracedo, Ruben Fernandez-Boullon, Pedro Celard et al. (2026). Automated grading of Linux/bash examinations using large language models: a four-level cognitive taxonomy approach. arXiv (preprint). — arxiv.org